Start with a source table, not an AI summary
Product reviews can reveal confusing setup steps, missing features, recurring defects, and language customers use to describe their needs. But a polished summary is hard to act on if nobody can find the reviews behind it. Build a source table before asking an AI system to categorize anything. Give each review a stable internal ID, its original link, the review text, the product or version if known, and any available date or rating. If a platform does not provide a reliable direct link, record the closest available page and note that limitation rather than inventing a URL.
Keep the original wording separate from any interpretation. One review might mention a failed import, a slow screen, and an unclear error message; it may eventually support more than one issue. Preserving the full text lets a teammate check whether a proposed backlog item reflects the customer’s experience. It also makes it easier to correct a category later without collecting the review again.
Before sending reviews to an AI tool, remove information that is not needed for triage, such as names, email addresses, order numbers, or other identifying details. Check whether your team is allowed to process the reviews in that tool. A source link can remain in your internal table even if you omit it from the text submitted for classification.
Choose categories that lead to action
Define a small set of categories before processing the full collection. For example, a team might use bugs, usability friction, feature requests, performance, documentation, pricing feedback, and unclear. Categories should reflect how the team routes work, not just what sounds tidy in a report. Add a short definition and an example for each one so that similar reviews are treated consistently.
Ask the AI system to extract individual observations rather than force each review into one label. For every observation, request a category, a short neutral description, the supporting review ID, and an exact excerpt from the review. An instruction such as “Do not infer a root cause or promise a fix; mark ambiguous items as unclear” helps separate what a customer reported from what the team still needs to investigate.
Test the scheme on a modest batch and inspect disagreements. If many comments land in unclear, the categories may be too narrow, the reviews may lack detail, or both. Revise the definitions before scaling up. The aim is not perfect automated classification; it is a workable first pass that people can audit.
Group similar observations without erasing differences
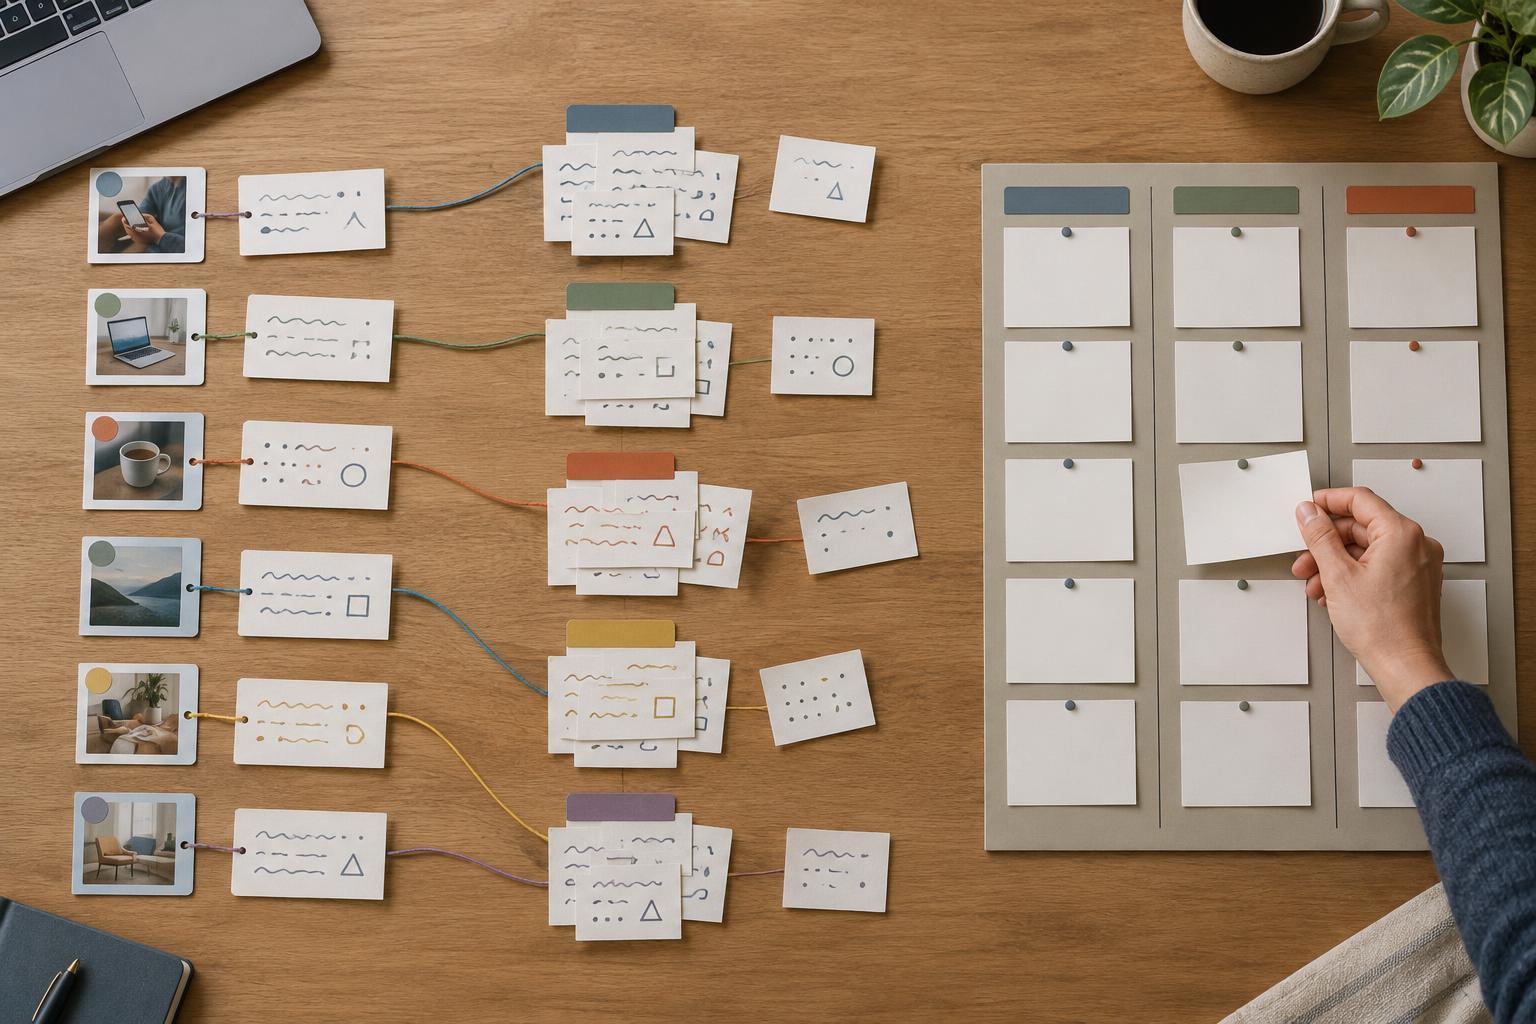
After extraction, group observations that appear to describe the same problem. Give each proposed issue a concise title, a description of the reported behavior, a category, and a list of supporting review IDs. Join those IDs back to the source table so the issue record contains the original links. Keep the excerpts too: they provide useful context if a link changes or a page becomes difficult to access.
Review proposed merges carefully. “Export fails” could refer to different file formats, devices, or steps. Conversely, customers may describe the same obstacle in very different words. If the evidence is thin, keep items separate or mark the relationship as possible rather than combining them into a single confirmed issue. Store each observation’s ID even after merging, so a later split does not require reconstructing the source trail.
Avoid presenting a count of reviews as a count of affected customers. One person may post more than once, and review platforms do not represent every user equally. A useful backlog can show how many source observations support an item while making clear what that number measures.
Make prioritization a human decision
The resulting backlog should help a team decide what to examine next, not automatically dictate a roadmap. Alongside each issue, record a review status such as needs validation, confirmed internally, planned, or closed. You can also add fields for the affected workflow, a team owner, and open questions. A reviewer can then check links, reproduce a reported behavior where possible, and decide whether the issue belongs in an engineering, design, support, or documentation queue.
AI can draft a suggested impact statement, but require it to identify the evidence it used. A review saying “I could not find the export button” supports a discoverability concern; it does not establish that export is broken for everyone. Keep severity and priority separate. Severity describes the potential effect of a problem, while priority also depends on factors outside the reviews, including team goals and the effort needed to investigate.
Build a repeatable check before importing
For each new batch, check that every extracted observation has a valid source ID, every proposed issue retains at least one source link, and every quoted excerpt appears in its associated review. Flag missing or mismatched fields for manual review. These checks can live in a spreadsheet or a small script; the important part is that a fluent AI response cannot silently become an unsourced backlog item.
Import approved issues into your team’s tracker with links and review status intact. Keep a record of the category definitions and the prompt or instructions used for each batch, so later changes are understandable. As new reviews arrive, attach relevant observations to existing issues or open new ones when the evidence differs. The result is a backlog that remains useful because teammates can move from a proposed issue back to the words that prompted it.


