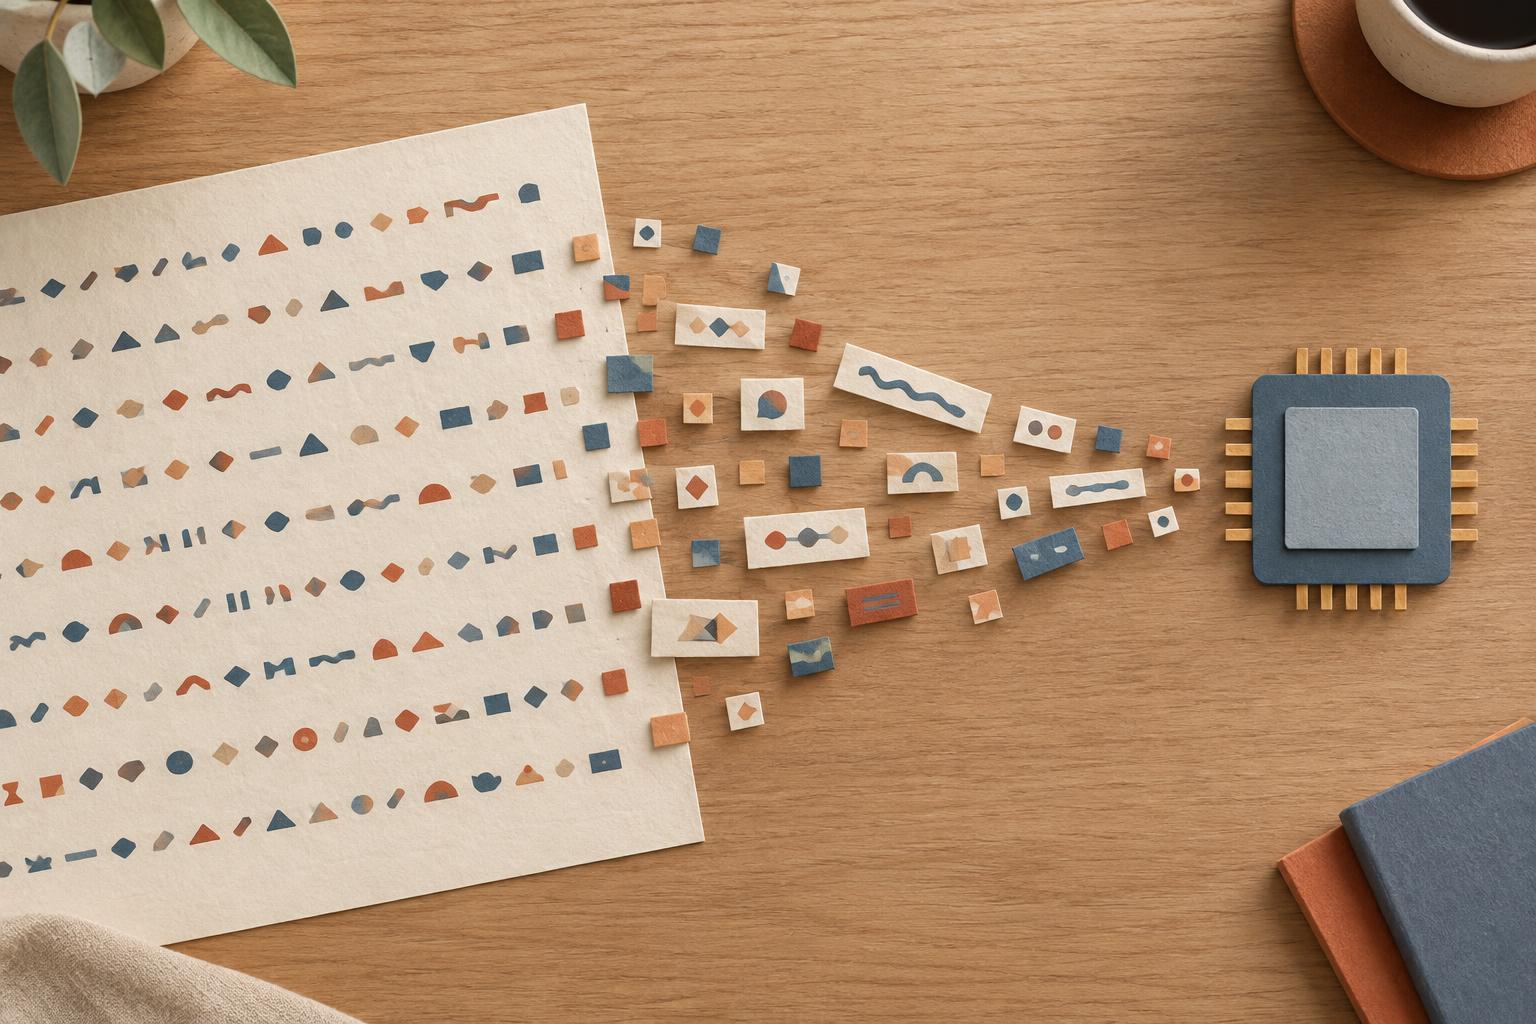
A token is a unit of text, not necessarily a word
When you type a question into a language model, the model does not receive it as a list of words in the way a person might read a sentence. A tokenizer first converts the text into smaller units called tokens. A token might represent a whole word, part of a word, a space attached to a word, a punctuation mark, or another piece of text. Each token is assigned an ID that the model can process.
For example, a familiar word may fit into one token, while a less familiar technical term may be divided into several pieces. Two versions of what looks like the same phrase can also split differently if capitalization, spacing, or punctuation changes. There is no universal token count for a sentence: it depends on the tokenizer used by the particular model.
Why split text this way?
Treating every complete word as its own unit would be awkward. Languages contain many words, and people continually create new names, abbreviations, and spellings. Subword pieces let a model handle text it has not encountered as a complete word by combining smaller units. Tokenizers can also preserve distinctions that matter in writing, such as punctuation and spaces.
Tokenization is a preparation step, not an act of understanding. After text becomes token IDs, the model works with learned numerical representations of those tokens and their positions in the sequence. It uses patterns learned during training to predict what token should come next. This does not mean it considers only the last token: its prediction can draw on earlier tokens that fit within the available context.
What tokenization changes in practice
Tokens matter whenever an AI tool sets a context limit. The context is the material the model can consider for a response, such as your message, earlier conversation, pasted documents, and sometimes tool output. Its limit is usually measured in tokens rather than words or pages. A document that looks short to a reader can use more tokens than expected if it contains code, unusual formatting, or many unfamiliar terms. The exact count varies by model.
Output also consumes tokens. If a response stops before finishing, an output limit may be one possible cause, though the tool may have other constraints. Splitting a large task into smaller, clearly labeled parts can help: provide the relevant source material, ask for one deliverable, then continue with the next. Trimming repeated instructions and irrelevant background leaves more room for the content the model needs.
Some services measure usage or set limits by token count. If that matters for your workflow, check the limits and counting method published by the tool you use rather than estimating from word count alone. A tokenizer counter supplied for one model may not give the same result for another.
Why spelling and formatting can matter
Because tokenization preserves details of the input, small edits can change the sequence the model receives. A product name with an unusual spelling, a file path, or a line of code may be broken into multiple pieces. That does not mean the model cannot work with it, but it is a reason to provide exact names and enough context when precision matters. If an identifier must be copied exactly, say so and verify it in the answer.
Token boundaries are not a reliable way to predict every mistake. A model can still handle a word split into several tokens, and it can still misinterpret a familiar word represented compactly. Likewise, a confident answer does not prove that the model counted characters, checked a calculation, or verified a fact. For tasks where exact characters or counts matter, inspect the result or use a suitable checking tool.
A useful mental model for prompting
Think of tokens as the pieces that connect your written instructions to the model’s processing, not as a secret language you must master. Most prompts benefit more from clear goals, relevant context, and an explicit output format than from attempts to manipulate token boundaries. If you ask for a summary, specify what to prioritize. If you provide a long document, identify the portion the model should use and the question it should answer.
This mental model also encourages careful review. A model generates an answer piece by piece; it does not automatically confirm that every sentence is true or that every requested detail survived a long conversation. Knowing what tokens are helps you plan around length limits and understand why word counts are imperfect estimates. Knowing what tokens are not helps you avoid treating tokenization as an explanation for everything an AI model can or cannot do.


