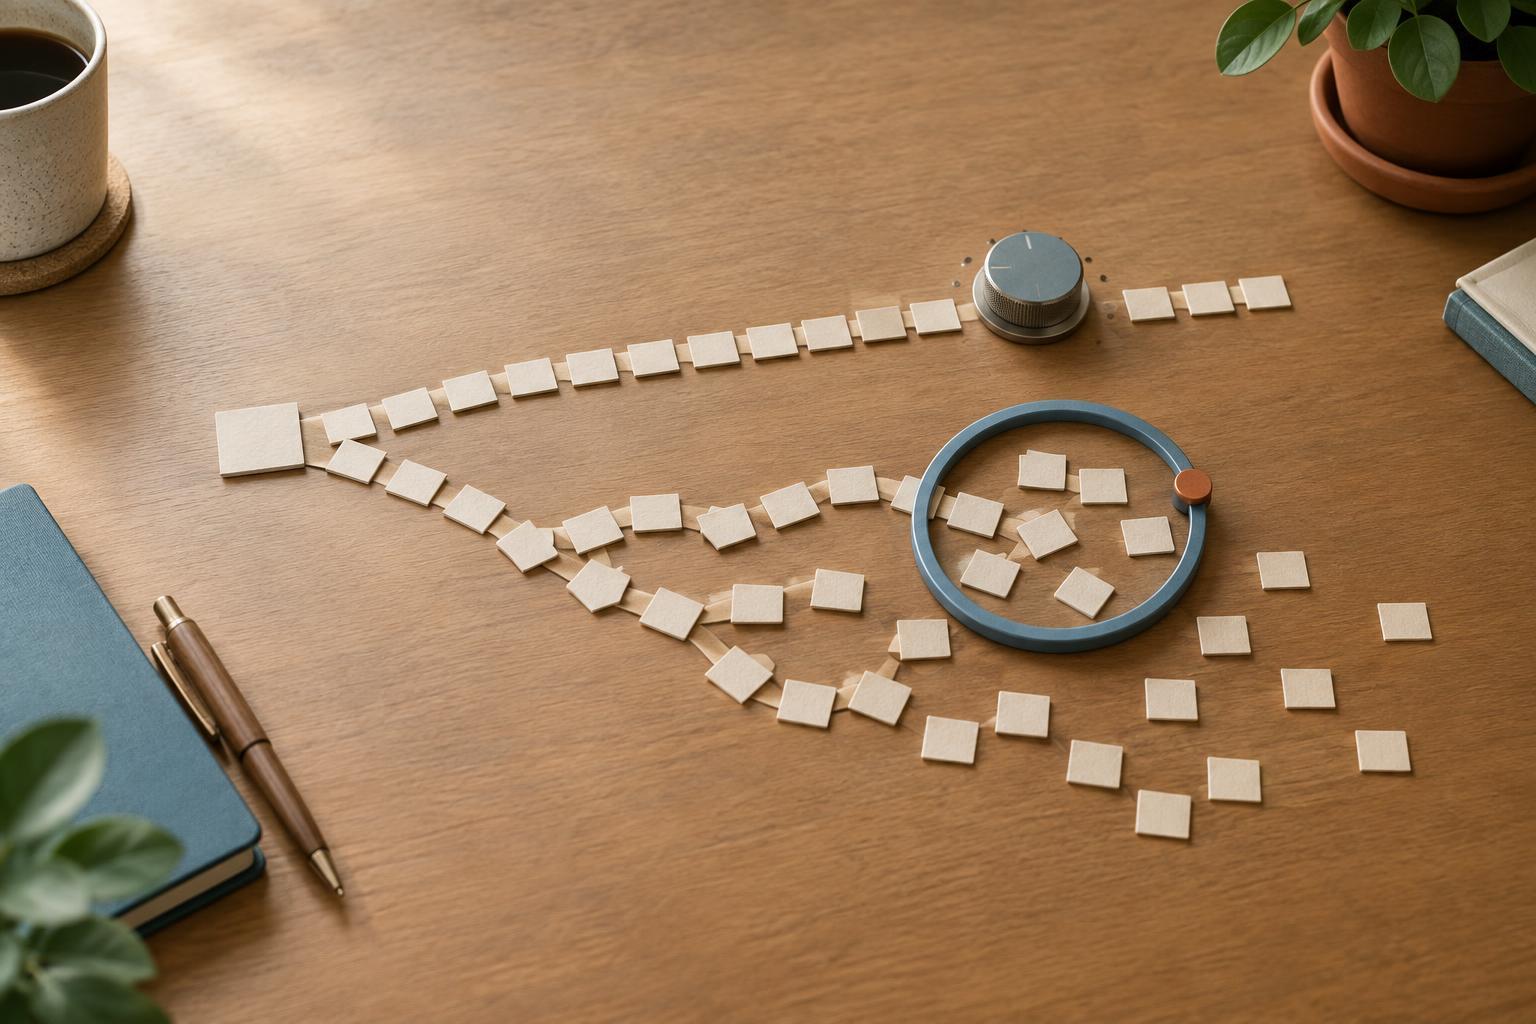
Where sampling fits in text generation
A language model generates text one token at a time. A token may be a word, part of a word, or a punctuation mark. At each step, the model assigns scores to possible next tokens based on the prompt and the text it has produced so far. Those scores are converted into probabilities, and a selection method chooses the next token. The process then repeats.
Temperature and top-p are controls for that selection process. They do not add knowledge, improve the model’s reasoning, or change what was in its training data. Instead, they affect how readily it chooses a less likely continuation. That can change the wording, structure, and direction of an answer, especially when many plausible continuations exist.
Temperature changes the shape of the choices
Temperature adjusts the relative probabilities of the available tokens. A lower temperature makes the model favor its highest-scoring options more strongly. A higher temperature spreads probability across more options, making less likely choices easier to select. Imagine the model could continue a sentence with several sensible words: low temperature concentrates its choices near the front-runners, while higher temperature gives the alternatives more of a chance.
This is why low temperature is often useful for tasks that benefit from consistency, such as extracting fields or following a fixed format. Higher temperature can help when exploring names, story directions, or different ways to phrase an idea. Neither setting guarantees a particular result. A low-temperature answer can still be wrong, and a high-temperature answer can still be repetitive.
Some interfaces allow a temperature of zero, which generally means choosing the most favored next token rather than sampling freely. Do not assume this makes every run identical: ties, system behavior, model updates, and other implementation details can still affect the output.
Top-p limits the pool of possible tokens
Top-p, also called nucleus sampling, takes a different approach. The model’s possible next tokens are ordered by probability, and the selection pool is limited to the smallest group whose combined probability reaches the chosen threshold. With a smaller top-p value, fewer alternatives are usually eligible; with a value closer to one, more of the probability distribution remains available. The size of that pool can change from one token to the next.
Unlike a fixed limit on the number of eligible tokens, top-p adapts to how confident the model is at each step. If one continuation dominates, the eligible pool may be small. If probability is spread across many reasonable continuations, it may be larger. The exact result also depends on the service’s implementation and its other generation settings.
Temperature reshapes probabilities; top-p restricts which choices can be sampled. When both are available, they can interact, so changing two controls at once makes the effect harder to interpret. For routine use, start with the application’s defaults and adjust one setting at a time.
Choose settings to match the task
For a constrained task, first make the instructions clear: specify the fields you need, the allowed format, and how to handle missing information. Then try a lower temperature if outputs vary more than you want. If your interface exposes top-p, leaving it at its default while testing temperature gives you a simpler comparison. Sampling settings cannot compensate for an ambiguous prompt or ensure that the model follows every constraint.
For brainstorming, try a somewhat higher temperature if the first responses feel too similar. Ask for distinct approaches, audiences, or constraints as well; that often helps more than increasing randomness alone. Raising temperature too far may produce ideas that are less relevant or harder to use. Lowering top-p may narrow the choices, but it does not reliably make an answer more factual.
When comparing settings, keep the prompt, model, and other available controls the same. Run several attempts and judge the outputs against your task: accuracy for a summary, valid structure for extracted data, or useful variety for ideas. A single striking response is not enough to show that a setting works better for your workflow.
What sampling settings cannot fix
A confident-sounding error is still an error, whether it appears at a low or high temperature. If an answer matters, check its claims against appropriate material rather than treating consistent wording as evidence. For tasks involving private information, decide what may be shared with the AI service before you write the prompt; temperature and top-p are not privacy controls.
Think of these settings as ways to steer variation, not as quality dials. Start with a clear task and the default settings, change one control when you have a specific problem to solve, and evaluate the resulting work. That simple approach is more useful than searching for one temperature and top-p combination that supposedly fits every prompt.


