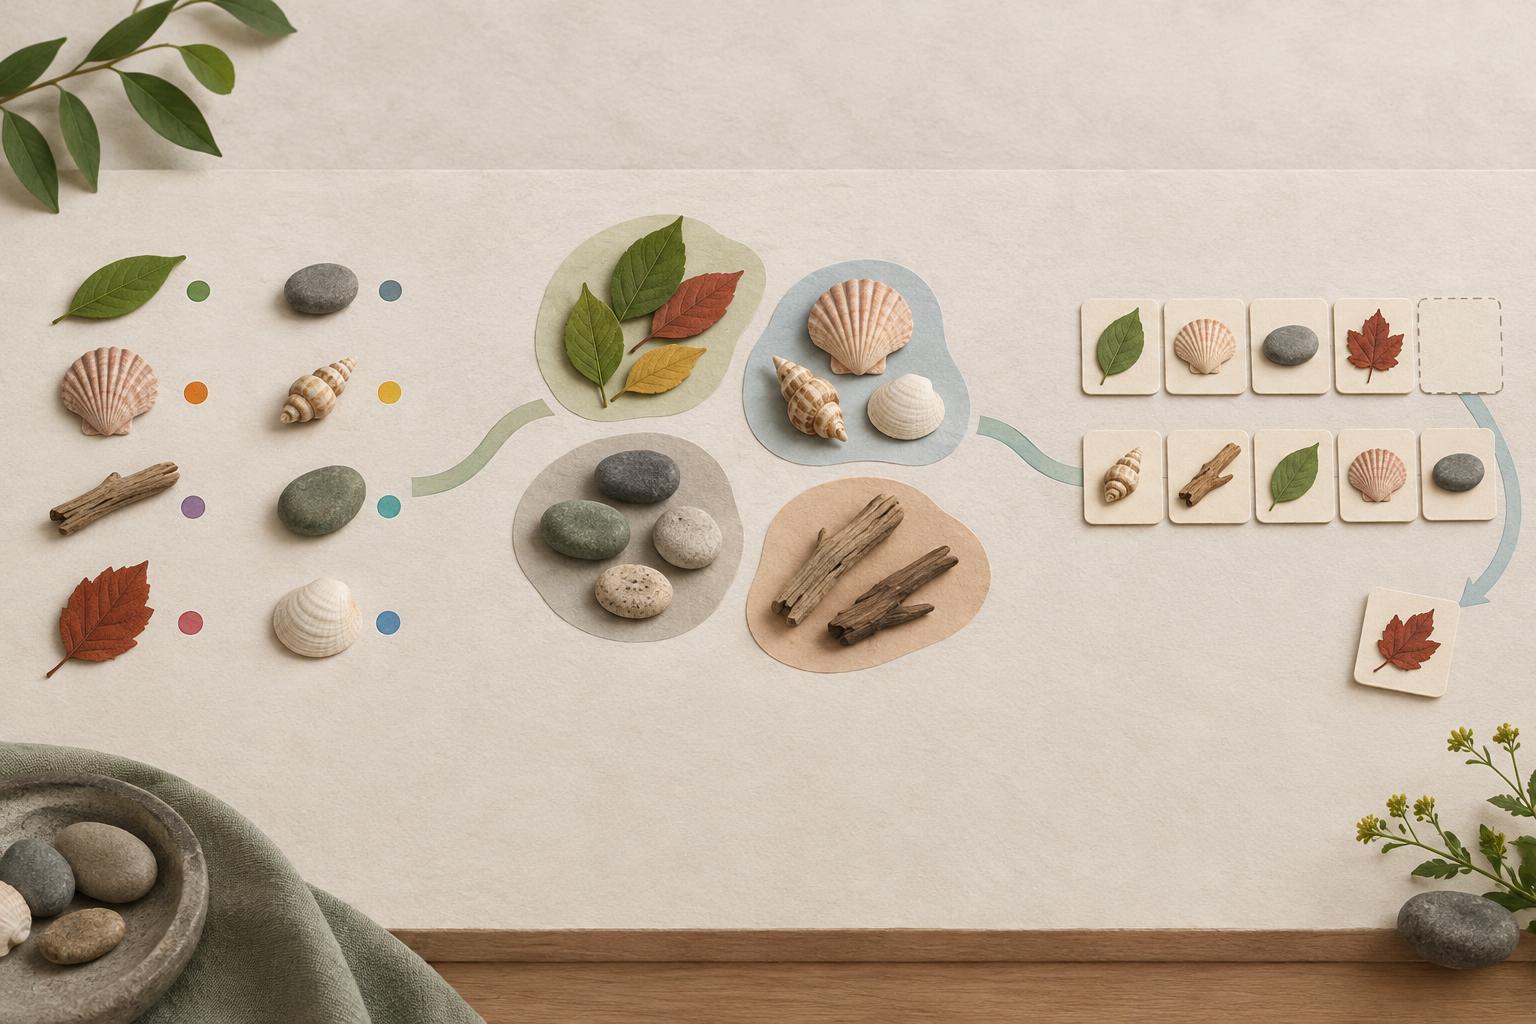
Start with the learning signal
Machine learning systems improve by adjusting their behavior in response to training data. The key difference between supervised, unsupervised and self-supervised learning is where the learning signal comes from: a provided answer, a pattern in the data, or a task constructed from the data itself. These terms describe training approaches, not three fixed kinds of product. A single AI system may use more than one.
Imagine a small team with a collection of customer messages. It could train a model to assign categories that staff have already chosen, explore whether messages form useful groups, or learn general features of the messages before training for a specific task. Each approach answers a different question, so choosing one starts with deciding what outcome would actually help the team.
Supervised learning: learn from examples with answers
In supervised learning, each training example comes with a target supplied from outside the model. A message might be labeled “billing,” “delivery” or “account access.” The model learns to predict those labels for new messages. Targets can also be numbers, such as an estimated delivery time rather than a category.
This approach fits a task with a clear desired output and enough relevant examples to show what that output means. It also makes evaluation relatively direct: set aside examples the model has not trained on, then compare its predictions with their known targets. Good results on that test do not guarantee good results everywhere, though. If the labels are inconsistent or future messages differ from the training examples, performance may suffer.
For a small team, the work is not just collecting examples. People must agree on what each label means, handle ambiguous cases and decide what should happen when the model is uncertain. A classifier that occasionally routes a message for human review may be more useful than one forced to make every decision alone.
Unsupervised learning: look for structure without target answers
Unsupervised learning works with data that has no provided target for the task at hand. Instead of learning to match staff-assigned categories, a system might group similar customer messages or represent them so that nearby items share features. Other methods can reduce a large set of measurements to a smaller representation that is easier to inspect.
The results need interpretation. A cluster might reflect a useful distinction between account problems and product questions, but it might also reflect message length, language or repeated wording. The system has found structure according to its method; it has not established that the structure matches the team’s priorities. Reviewing examples from each group can reveal whether the output is worth using.
This approach is helpful for exploring an unfamiliar collection or preparing a later workflow. If staff discover a recurring type of request, they can define a label and begin collecting supervised examples. Unsupervised output can suggest that next step, but it does not replace a decision about what matters.
Self-supervised learning: create a task from the data
Self-supervised learning also avoids requiring a person to label every training example, but it creates a specific prediction task from the data itself. For text, a system might hide part of a passage and learn to predict the missing content. In another setup, it might learn to predict what comes next. The passage supplies both the input and the target without someone manually writing an answer for each example.
That task can help a model learn representations useful beyond the original exercise. A text model trained this way may later be adapted for classification, search or other applications. This is one reason self-supervised training is often used before a more specific training stage. It is not a guarantee that the resulting model understands a topic, follows instructions reliably or gives accurate answers. Predicting patterns in training data is different from checking a claim against evidence.
The boundary between these approaches is worth keeping clear. Self-supervised learning has targets, but they are generated from the available data rather than supplied as independent human judgments about the intended task. It can be part of a broader workflow that later includes supervised training.
Choose by the job, then check the result
If you have a defined decision and trustworthy labeled examples, supervised learning is a natural starting point. If you need to inspect a collection before defining categories, unsupervised methods may help you discover candidate groupings. If you have substantial raw data and want a reusable starting representation, self-supervised training may be relevant, though training a model from scratch can be impractical for a small team. Using an existing model may be the simpler route.
Whichever approach you choose, test it against the job you need done. Check examples outside the training material, examine mistakes and decide when a person should take over. Also consider whether the data includes private information and whether it is appropriate to use for training. The learning method explains how a model receives feedback; careful evaluation determines whether its output is useful.


