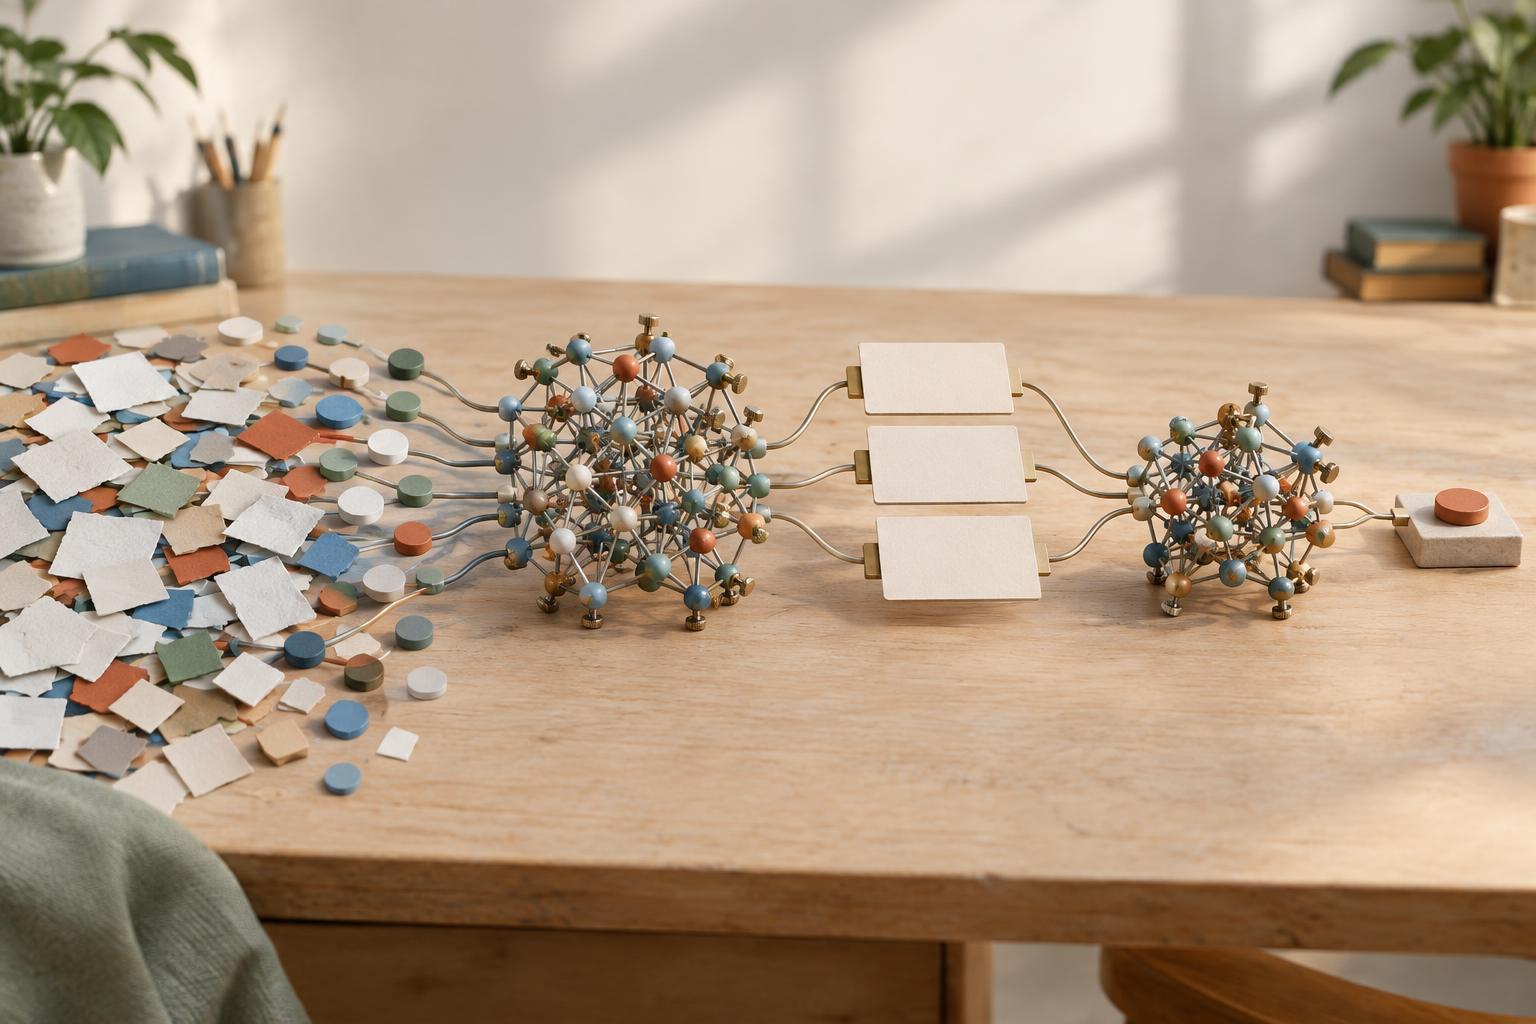
Start with the model’s weights
A language model produces text using numerical settings called weights. Training changes those weights. A prompt does not normally change them: it gives the model information and directions to use while producing a response. This distinction helps explain why a model can answer a question from a document you paste into a chat without having learned that document permanently.
Pretraining, instruction tuning and fine-tuning all involve training, but they serve different purposes. Pretraining builds broad capabilities. Instruction tuning teaches a model to respond to requests in a more useful format. Fine-tuning is the broader term for additional training on a selected dataset or task; instruction tuning is one kind of fine-tuning. The words are sometimes used differently in product descriptions, so it is worth asking what data and training objective a provider means.
Pretraining builds a general-purpose starting point
During pretraining, a language model learns from a large collection of text and, for some models, other types of data. A common training task is to predict a missing or next piece of content from what came before it. Repeating that task across varied material adjusts the weights so the model can represent patterns in language, code, structure and relationships between concepts.
The result is often called a base model. It may be able to complete a paragraph, imitate a format or answer some questions, but it has not necessarily been trained to treat a user’s request as an instruction to follow. For example, when given a question, a base model might continue with more question-and-answer examples rather than provide the direct answer a person expects.
Pretraining is not the same as storing an accurate reference library. A model can generate a plausible explanation while getting a fact wrong, and it may not know where a particular claim came from. Its behavior depends in part on its training data and design, which may not be fully visible to the people using it.
Instruction tuning teaches the model how to respond
Instruction tuning takes a pretrained model and trains it on examples that pair a request with a desired response. The examples might show the model how to answer a question, summarize a passage, follow formatting constraints or explain a refusal. This stage aims to make the model more useful in an assistant-style conversation, not to rebuild its broad understanding from scratch.
Some developers use additional training methods to encourage responses that people prefer or to discourage certain behavior. Those methods are related to, but not identical to, instruction tuning. The exact sequence varies by model: a simple three-stage diagram is a helpful mental model, not a rule every AI system follows.
Instruction tuning can improve how a model interprets and follows requests. It does not guarantee that its answers are true, that it will obey every constraint or that it will handle every unfamiliar situation well. A polished response is evidence of fluent output, not evidence that the underlying claim has been checked.
Fine-tuning adapts a model for a narrower purpose
Fine-tuning means continuing to train an existing model using selected examples. A team might fine-tune a model to produce a consistent output structure, use specialized terminology or handle a recurring classification task. Because instruction tuning also continues training an existing model, it fits under this broad definition. In everyday use, however, people often say “fine-tuning” to mean a later, task-specific adaptation after an assistant model is already available.
Fine-tuning works best when the desired behavior can be demonstrated with suitable examples and evaluated against a clear goal. It is not automatically the best way to give a model changing information. If a small team needs answers grounded in its current handbook, supplying relevant excerpts at request time may be easier to update than training on each revision. That approach provides context for a response without changing the model’s weights.
Before fine-tuning, define what success looks like, check that you have permission to use the training material and keep examples aside for testing. Look for both improvements and regressions: a model adapted to one style or task may become less useful elsewhere. For any important output, review the result rather than assuming that an extra training stage has made it reliable.


