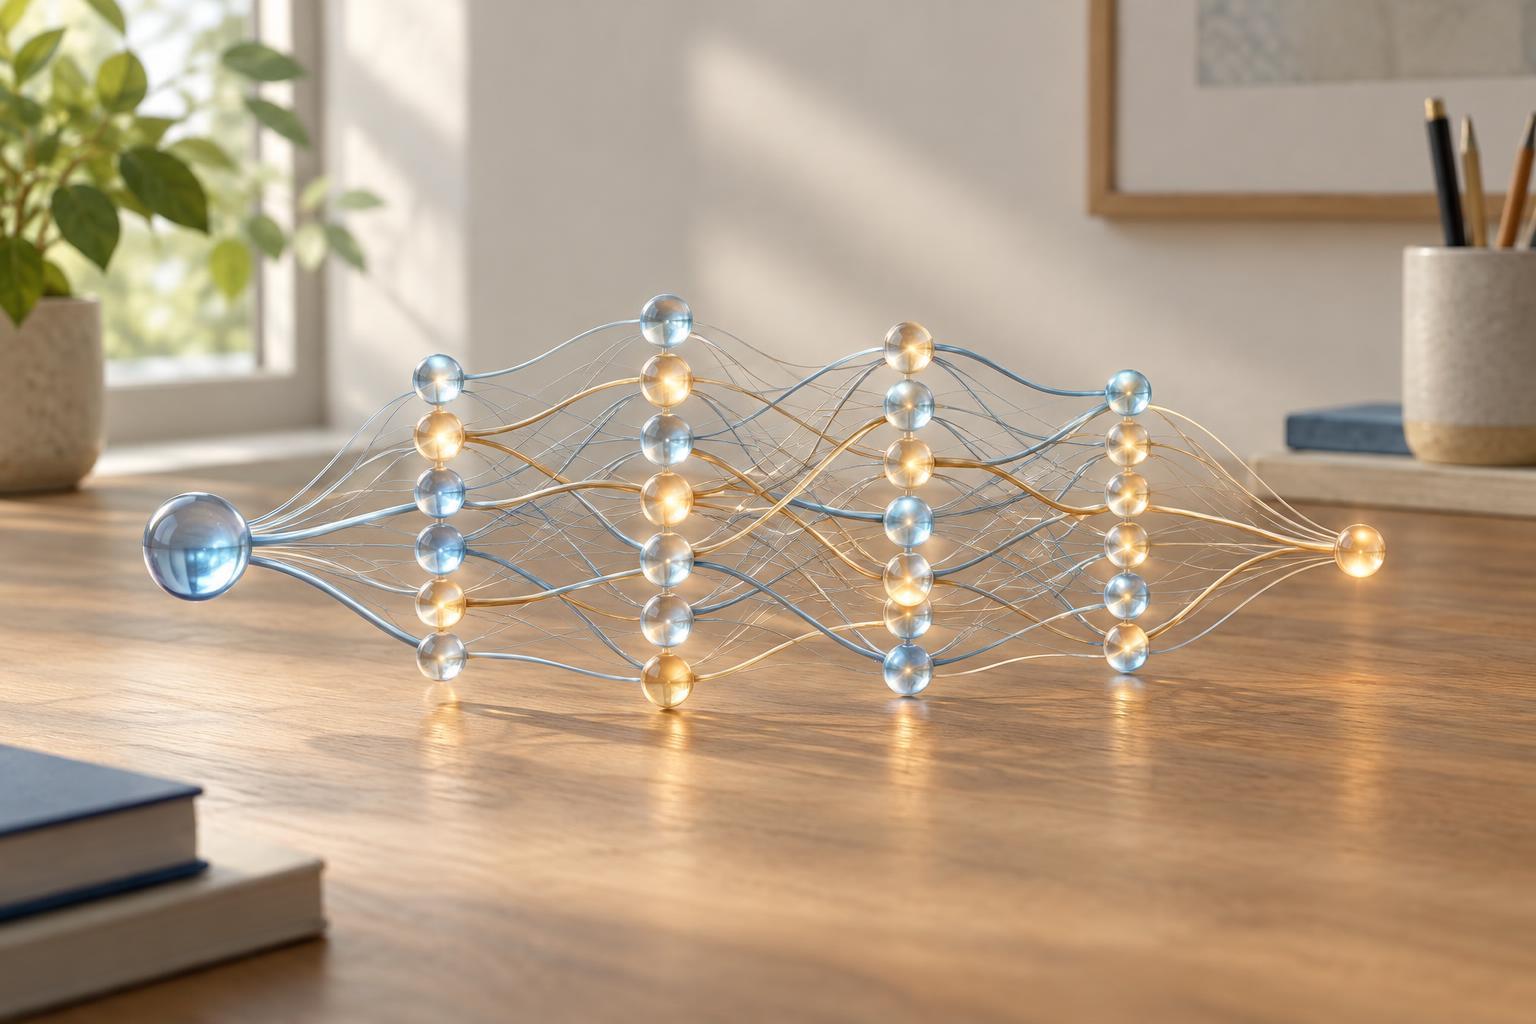
A network is a chain of calculations
A neural network is a system that learns to map inputs to outputs. The input might be numbers representing pixels, words or measurements; the output might be a category, a predicted value or the next piece of text. Between them, the network performs a series of calculations arranged in layers. Each layer receives numbers, transforms them and passes numbers to the next layer.
You can think of a layer as a stage in a workflow, but it does not come with a built-in rule such as “detect a face.” Its behavior depends on values learned during training and on the stages around it. In many networks, earlier layers produce intermediate representations that later layers can use. What those representations mean is not always obvious from inspecting individual numbers.
Weights decide how strongly signals matter
A common building block takes several input numbers, multiplies each by a weight, adds the results and often adds a separate value called a bias. A large positive weight makes an input push the result upward; a negative weight pushes it downward. The bias shifts the result even when the inputs are small. Together, these values determine how the building block responds to a particular combination of inputs.
For a simple example, imagine a model using word-related signals to sort messages by topic. One learned weight might make a signal associated with “invoice” contribute to a billing category. That does not mean the model has a permanent dictionary entry saying that “invoice” always means billing. Other words, context and later calculations can change the final result. Weights are useful because many small contributions can be combined, but an individual weight rarely provides a complete explanation of a complex model’s decision.
Activations make layered learning more flexible
After combining its weighted inputs, a building block often applies an activation function. This function changes the resulting number before it moves onward. Some activations suppress negative values; others smoothly limit or reshape values. The choice of function depends on the network design and the job it is meant to do.
Activations matter because they introduce nonlinearity. If every layer only multiplied and added numbers, stacking more layers would still amount to one large linear calculation. Nonlinear activations let layers build on one another to represent more complicated relationships. For instance, a later stage can respond to a particular combination of signals rather than simply adding each signal’s independent contribution. An activation is not a moment when a machine “understands” something; it is a mathematical operation that helps the network produce flexible outputs.
Training changes the weights, not the basic arithmetic
Before training, a network’s weights generally do not produce useful results. During training, it processes examples, makes outputs and compares those outputs with a target using a measure called a loss. An optimization method then adjusts weights and biases to reduce that loss across examples. A widely used approach, backpropagation, calculates how changes to different values would affect the loss, making those adjustments more efficient.
Training is different from using a trained model. When you submit an input to a model in ordinary use, it typically runs calculations with its existing parameters to produce an output; your input does not automatically retrain all its weights. Some products may separately store conversation context or use feedback in later training processes. Knowing which kind of change is happening matters when you evaluate claims that an AI system has “learned” from a single interaction.
What this picture explains—and what it does not
Layers, weights and activations provide a useful foundation, but real networks vary. Some connect information across different parts of an input, while others are designed for sequences or images. Modern language models also use mechanisms such as attention to combine information from context. Despite those differences, the central idea remains: learned numerical values shape a series of transformations from input to output.
Successful training does not guarantee a reliable answer. A network can pick up patterns that do not hold in a new situation, reflect problems in its training examples or produce a confident-sounding mistake. For practical use, ask what task the model was trained to support, test it on examples that resemble your own work and verify consequential outputs independently. Understanding the basic mechanics helps you ask better questions without assuming every internal number has a simple human-readable meaning.


