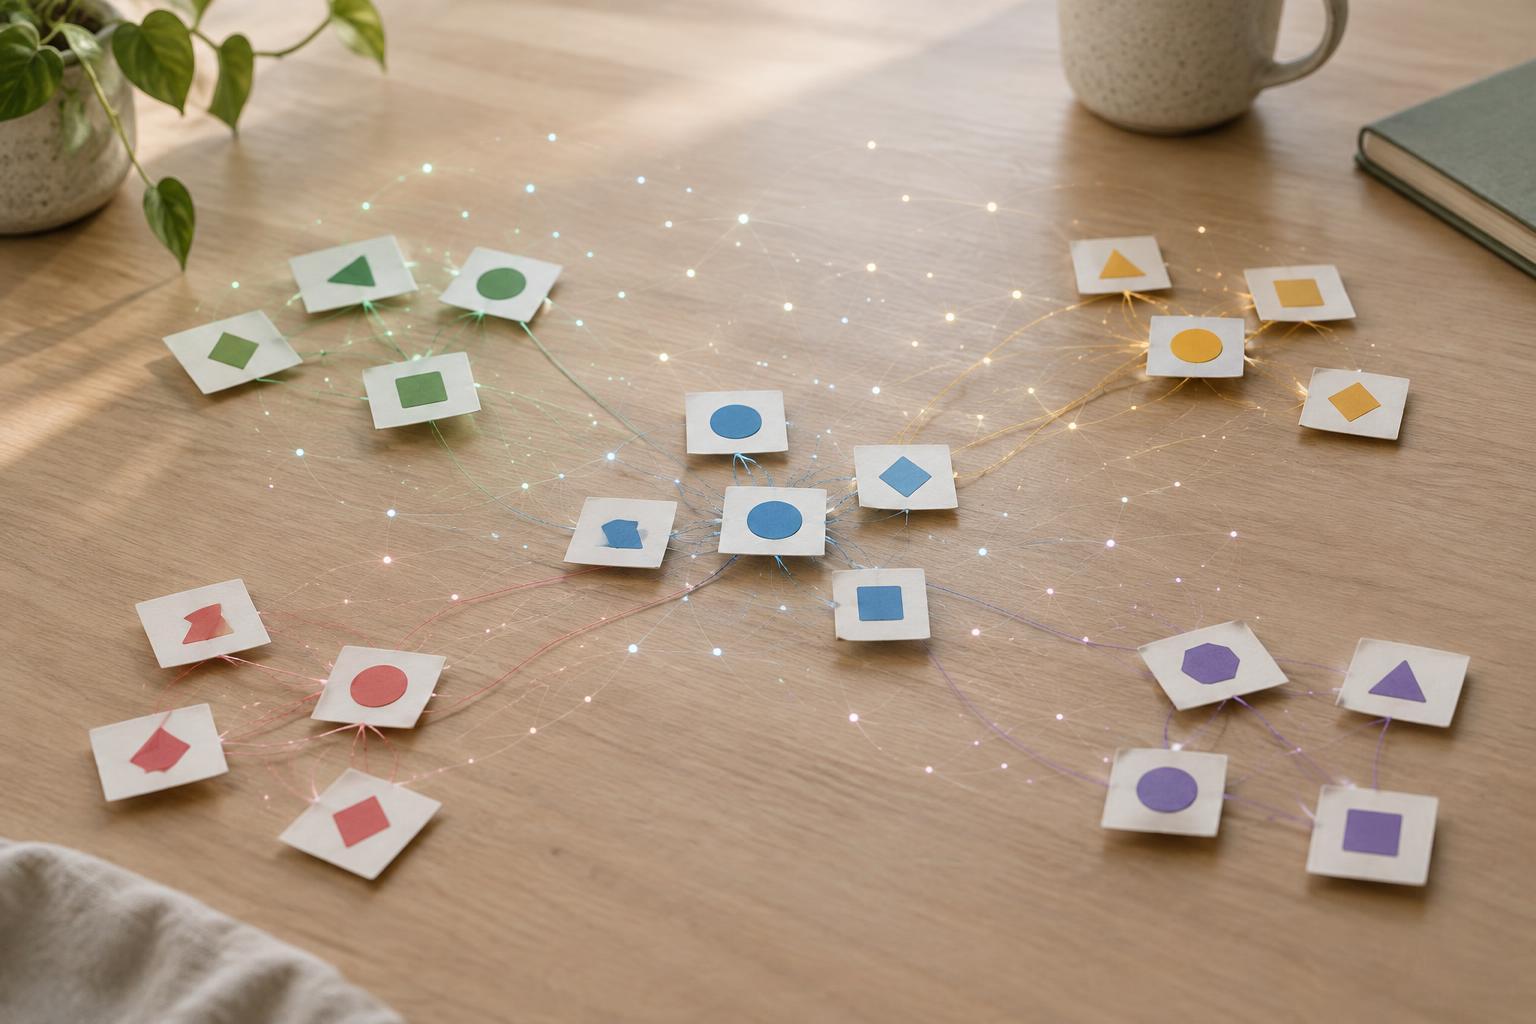
What an embedding represents
An embedding is a list of numbers produced by a model from an input such as a sentence, document excerpt, image or audio clip. That list is called a vector. Its numbers are not a readable summary: you generally cannot point to one position and say it means “customer support.” Instead, the positions work together to place the input within a mathematical space learned by the model.
In a useful embedding space, inputs with related meanings or patterns tend to have vectors that are close together. A search for “how do I change my password?” might therefore find a help article titled “Reset your account credentials,” even though the wording differs. This is the main appeal of embedding-based search: it can look beyond exact keyword matches.
An embedding does not capture everything about its source. It is a compressed representation shaped by the model and its training. Two passages can appear similar to the model while differing in an important detail, such as a product name, a negation or a version number.
How similarity search works
A basic workflow starts by preparing the content you want people to search. For a collection of documents, you might divide long files into smaller passages, keep a link or identifier for each passage, and generate an embedding for each one. You then store the vectors alongside the information needed to retrieve their original text.
When someone enters a query, the system creates a vector for that query using a compatible embedding model. It compares the query vector with stored vectors and returns nearby items. One common measure is cosine similarity, which compares the direction of two vectors. For larger collections, a vector index can find likely neighbors without comparing every stored vector one by one.
The result is a ranked set of candidates, not proof that the top passage answers the question. A search for “cancel a subscription” could surface instructions for pausing one instead. Showing the original passage, its title and its location gives a person a way to check whether the match is genuinely useful.
The choices that shape results
Chunk size matters. If you embed an entire long document as one vector, a brief but relevant detail may be hard to find. If you split it into tiny fragments, a result may lose the context needed to interpret it. A practical starting point is to split at natural boundaries, such as headings or paragraphs, and inspect whether retrieved passages contain enough information to stand on their own.
Use the same embedding model, or a model pair designed to work together, for the content and the queries. Vectors from unrelated models are not automatically comparable. If you change models later, you may need to generate new embeddings for stored content. Keep document identifiers and model information so the collection is easier to maintain.
Embeddings also need not replace other search methods. Keyword search can be valuable when exact terms matter, including error codes, names and identifiers. Combining keyword and vector results, then applying filters such as document type or product area, can produce more useful candidates than relying on semantic similarity alone.
A small, testable use case
Suppose a small team wants to search its internal how-to guides. It can begin with a limited set of approved documents, split them into passages and save each passage with its source title. After generating embeddings, the team can try questions people actually ask and review the returned text rather than judging results solely by similarity scores.
Useful tests include questions whose answers exist, questions whose answers do not exist, and questions with easily confused terms. Does a query about deleting an account return a passage about merely signing out? Can a person tell which guide a result came from? These checks reveal problems that a single impressive example will miss.
If the results will feed an AI assistant, retrieval is only one step. The assistant may still misread a passage or present an unsupported answer confidently. Providing the retrieved text as context and asking the assistant to indicate when that context is insufficient can help, but the complete workflow needs its own testing.
Limits, privacy and maintenance
A vector is not a safe, anonymous substitute for sensitive content. Embeddings can preserve information about what an input concerns, and the search system may also store the original passage. Before indexing private material, decide what may be included, who can search it, how access controls apply and when stored data should be removed.
Finally, search quality can change as documents change. Update or delete vectors when their source passages change, and keep a path from every result back to the current source. Embeddings are most useful when treated as a way to propose relevant material for inspection—not as an authority on what is true.


